Mitigating Friction in High-Stakes Vendor Integration Programs
The Costly Reality of Vendor Integration Friction
Enterprise transformation increasingly depends on specialized external engineering firms, systems integrators, cloud partners, and software vendors. That model expands access to scarce expertise and accelerates delivery, but it also creates more handoffs. Each handoff introduces the possibility that one organization”s definition of ready, complete, secure, or urgent will differ from another”s. The resulting delays rarely appear as a single dramatic failure. They accumulate through unanswered questions, duplicated work, late design changes, blocked environments, and decisions that remain unresolved until a release window is already at risk.
The underlying problem is often misdiagnosed as a contractual weakness. In practice, many programs have detailed statements of work, service levels, escalation clauses, and acceptance criteria. The friction arises in the space between those formal controls and the daily operating rhythm of delivery. A vendor may meet its response-time obligation while waiting three days for a client dependency. A client may believe a feature is included because it supports the agreed business outcome, while the vendor treats it as a change request. Contractual compliance can therefore coexist with declining momentum. The remedy is an operating bridge that makes assumptions visible before they become disputes.
Where Contracts End and Operational Reality Begins
A master services agreement establishes the legal relationship, but it does not automatically create a shared delivery system. Integrated sprint cycles require decisions about backlog refinement, architecture ownership, test data, access provisioning, release approvals, incident response, and the meaning of acceptance. Those decisions are often distributed across product, engineering, security, procurement, and vendor teams. If the contract describes outcomes without defining the working interfaces between those groups, the program inherits a coordination gap.
Several sources of friction recur across high-stakes programs. Teams may use different ticketing systems, repositories, documentation standards, or severity classifications. Dependencies may exist only in individual engineers” knowledge rather than in a visible register. A vendor optimized for rapid iteration may encounter an enterprise change-control process designed for regulated stability. Internal teams may interpret a question as a routine clarification, while the vendor sees it as an architectural decision requiring formal approval. These are not necessarily signs of bad faith. They are symptoms of incompatible operating assumptions.
The distinction between nominal SLA performance and actual delivery velocity is especially important. An SLA can measure uptime, response time, defect resolution, or staffing levels, while the program”s real constraint is an unresolved decision or an unavailable integration environment. Procurement management is designed to govern the broader lifecycle of external work, including planning, sourcing, performance control, acceptance, and closure. A useful governance ecosystem for shared services illustrates the same principle at institutional scale: diverse entities need common standards, accountable points of contact, and defined escalation paths to convert formal governance into coordinated action.
| Formal control | Operational question | Typical hidden risk |
|---|---|---|
| Response-time SLA | Who must provide the decision or dependency? | Fast acknowledgement without meaningful progress |
| Statement of work | How are ambiguous requirements interpreted? | Scope disputes appearing late in the sprint |
| Acceptance criteria | Who validates cross-system behavior? | Each party declaring its own component complete |
| Security controls | How are access requests and exceptions handled? | Compliant design blocked by slow provisioning |
Introducing the Dedicated Operational Liaison Model
A dedicated operational liaison is not a passive project manager who circulates status reports. The role is a structural bridge between organizations, with explicit responsibility for making the combined delivery system function. The liaison tracks where work crosses boundaries, identifies assumptions that are not yet shared, and ensures that an issue reaches the person able to resolve it. This is particularly valuable when a program includes several vendors whose incentives, terminology, and release cadences differ.
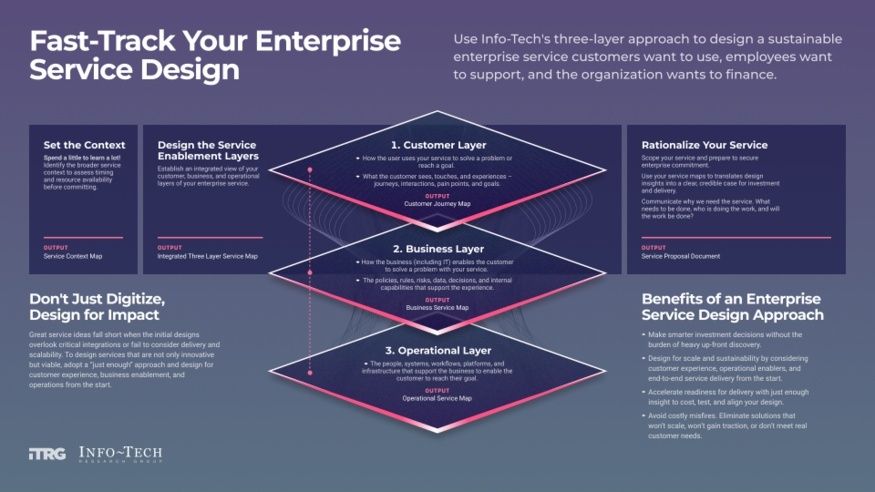
The liaison must combine technical fluency with organizational judgment. Systems thinking is required to understand how a small change in one component affects architecture, testing, security, operations, and commercial scope. Political neutrality matters because the liaison cannot become an advocate for one party”s narrative. At the same time, neutrality does not mean detachment. Effective coordination requires bidirectional advocacy: protecting the enterprise”s controls and outcomes while ensuring that vendor constraints are represented accurately rather than dismissed as resistance.
The model resembles the accountable coordination structures used in large public-sector operating environments. Senior accountable contacts and cross-functional governance groups exist because policy alone cannot coordinate every local decision. In a technology program, the liaison performs a comparable function at delivery level. Responsibilities should be explicit and measurable, including:
- Triaging backlog items that contain unclear ownership, dependencies, or acceptance conditions.
- Translating technical constraints into business, procurement, security, and schedule implications.
- Maintaining a decision and dependency register with named owners and due dates.
- Preparing escalations with evidence, options, impact, and a recommended decision.
- Checking that vendor commitments remain consistent with architecture and compliance guardrails.
- Maintaining a single cross-party view of risks, blocked work, and upcoming commitment points.
Tactical Mechanisms to Neutralize Scope Creep and Misalignment
Scope creep is often treated as a problem of discipline, but it frequently begins earlier, when teams commit to work before they share the same understanding of the problem. A practical response is to introduce discovery rituals before commitment horizons are locked. These sessions should include the product owner, relevant client architects, the vendor delivery lead, security or compliance representatives, and any team responsible for a critical dependency. The objective is not to design every detail in advance. It is to expose uncertainty while there is still time to adjust sequencing, staffing, or scope.
A liaison can make this process operational through a repeatable escalation framework:
- Capture the issue at the boundary where it appears, using a shared identifier linked to the relevant backlog item, system, or release.
- Classify the issue as a decision, dependency, defect, assumption, access constraint, or potential scope change.
- Assign an accountable owner and record the decision deadline, not merely the date on which the issue was raised.
- Assess impact across cost, schedule, security, architecture, quality, and downstream vendor commitments.
- Present a small set of viable options, including the consequence of taking no action.
- Escalate through a defined path when the deadline passes, rather than allowing the item to remain indefinitely in a meeting queue.
- Record the decision and communicate its effect on the backlog, release plan, and acceptance evidence.
Shared quality metrics then turn coordination into measurable control. Teams should agree on definitions for escaped defects, rework, blocked days, environment readiness, deployment success, test coverage, and decision lead time. Release thresholds must also be joint. A vendor should not be rewarded for deploying its component quickly if the integrated service cannot pass security, resilience, or end-to-end validation. The Government Accountability Office guidance on complex integrated system life cycles reflects the value of disciplined monitoring, risk management, and evidence-based oversight. In programs involving emerging AI interfaces, this need is even sharper because tool access, permissions, agent delegation, and audit trails can cross organizational boundaries quickly.
Institutionalizing Mutual Accountability Across Pipelines
Accountability becomes credible when the program can show where work is moving and where it is waiting. A unified observability dashboard should combine delivery signals from client and vendor environments, while respecting security and access boundaries. Useful views include open dependencies by age, blocked work by owner, cycle time by handoff, defect origin, environment availability, approval latency, and change requests by cause. The purpose is not to create a public scoreboard for blame. It is to expose bottlenecks that no single team can see from its own toolset.
Continuous feedback is more effective than punitive performance reviews conducted after a milestone has failed. A weekly operational review can focus on emerging friction, while a monthly governance session examines trends, capacity, commercial implications, and systemic risks. This approach allows leaders to distinguish between an isolated miss and a recurring process defect. It also protects the legitimate speed advantage of a third-party specialist without allowing speed to bypass enterprise architecture, privacy, security, or change controls. Recent partnerships aimed at moving enterprise AI from experimentation to deployment demonstrate the same balancing act: faster releases and redesigned workflows must coexist with governance, responsible use, and measurable value. Vendor access should therefore be continuously verified, scoped by least privilege, and monitored rather than treated as permanently trusted.
- Measure both activity and outcome, including integrated release success rather than component completion alone.
- Review client-side bottlenecks with the same seriousness applied to vendor performance.
- Use time-bound exceptions with named owners and expiry dates.
- Make architecture and compliance decisions visible to delivery teams before implementation begins.
- Reward early risk disclosure, because hidden risk is more expensive than reported uncertainty.
Turn Partnership Friction into Delivery Advantage
High-stakes vendor integration succeeds through human and operational architecture as much as through legal protection. Contracts define the boundaries of the relationship, but a dedicated operational liaison makes those boundaries workable in daily delivery. By translating constraints, aligning cadences, and escalating decisions before they become emergencies, the liaison protects budget and schedule while reducing the frustration that causes experienced people to disengage.
Leaders can begin with a focused diagnostic this week. Map every major handoff across client and vendor teams, identify dependencies that lack named owners, compare each party”s definition of ready and done, and review the last five delayed decisions for recurring patterns. Then test whether current dashboards show blocked work on both sides, not just vendor output. If the same questions repeatedly resurface, or if compliant work regularly waits for invisible approvals, the program does not have a motivation problem. It has an integration design problem. Establishing the liaison role, a shared decision register, joint quality thresholds, and a reliable escalation cadence provides the bridge from contractual intent to dependable delivery.